Observe a pipeline
Interpret tapstate pipeline status, metrics, snapshot progress, and node-local logs
Open the pipeline in the web application and use Monitoring and Logs to inspect its activity. Compare these observations with source and target data before treating a run as successful.
Inspect the web application
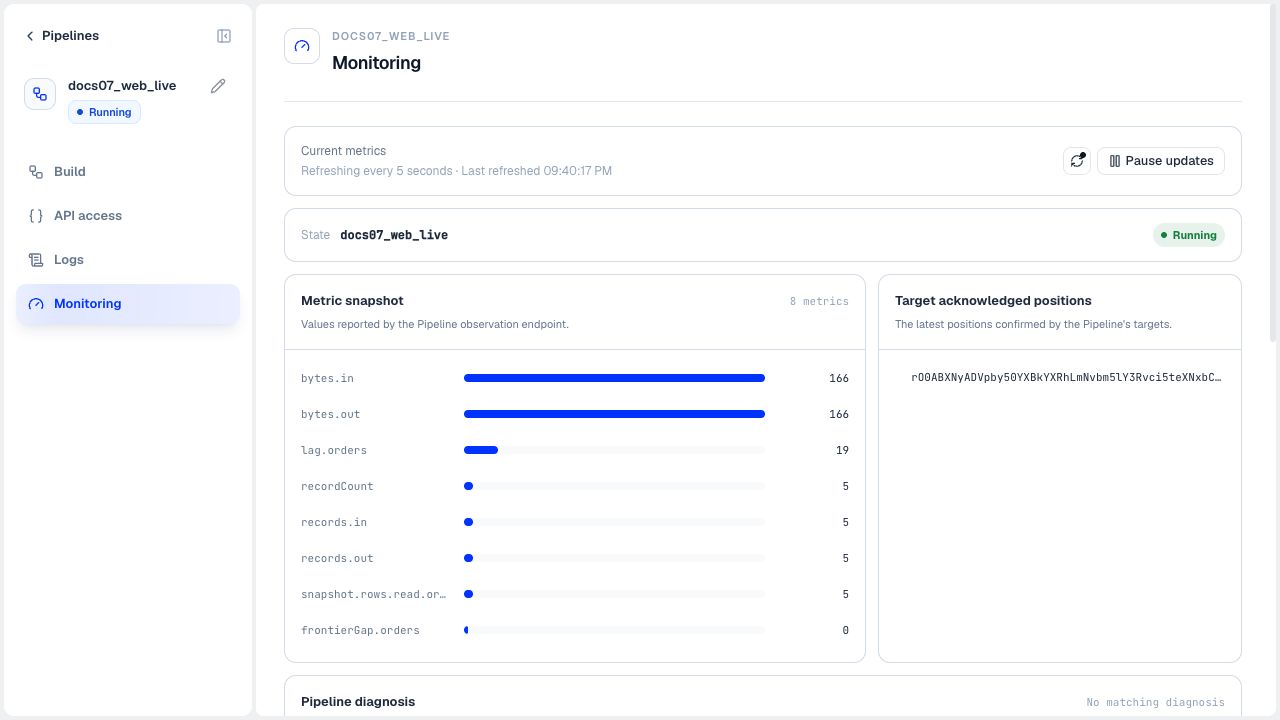
In Pipelines, open your pipeline and select Monitoring. Review its current metrics and target acknowledged positions. Use the refresh control to update the display, or pause automatic refresh while inspecting a value.
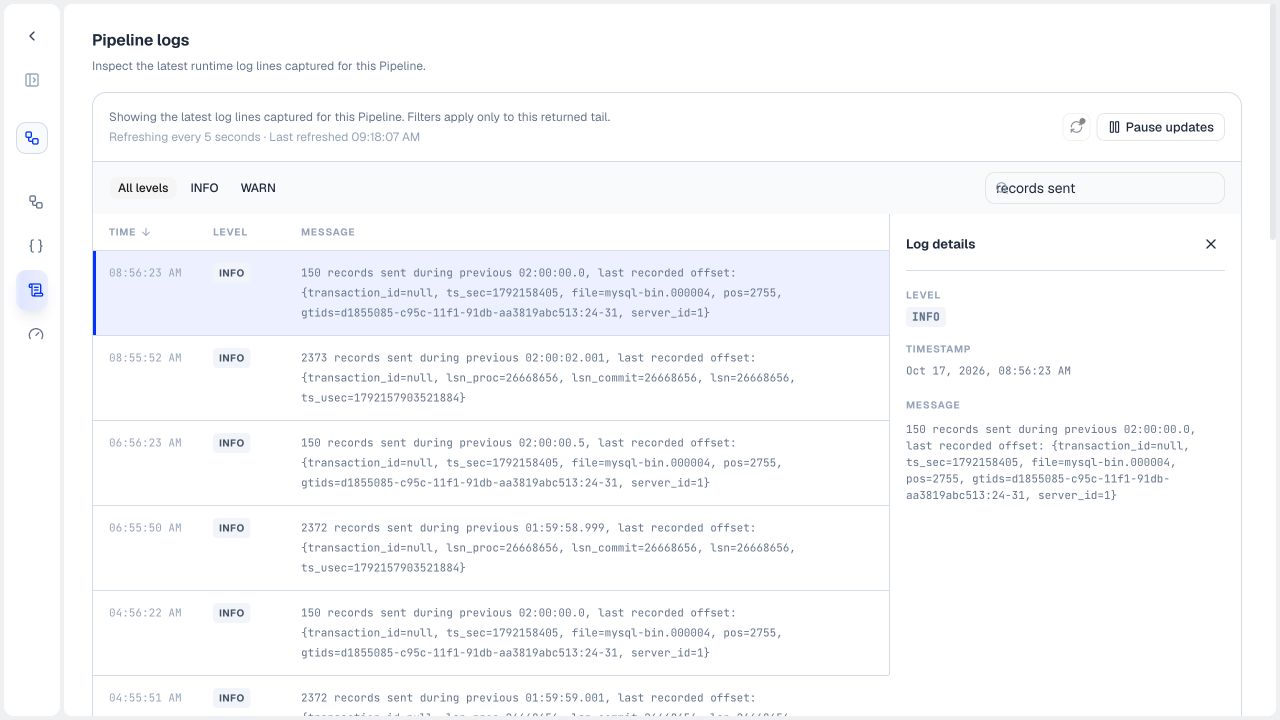
Select Logs to inspect recent runtime messages. Filter by level or use Search this log tail, then select a line to open Log details. These filters narrow the returned tail; they do not search a historical log archive.
CLI and API access
CLI, REST, and MCP expose the same underlying observations for troubleshooting and automation. The commands below assume an authenticated CLI session.
| Surface | Question | Storage boundary |
|---|---|---|
| Status | What is known about lifecycle intent and runtime state? | Pipeline catalog and latest available observation |
| Metrics | What numeric run statistics and per-table positions are available? | Latest store-backed observation |
| Snapshot | What per-table initial-load progress is available? | Latest store-backed observation |
| History | How did output rates and selected-table lag change? | Retained samples, 15 days by default |
| Explanation | What does the latest observation say about a failure or lack of progress? | Interpretation of current evidence |
| Logs | What did this process recently report for the pipeline? | Bounded node-local log tail |
Read status
status orders_to_operational_state
status orders_to_operational_state --watch
States include:
NEW: known to the server, with no runtime observation yet;RUNNING: executing;PAUSED: intentionally paused;STOPPED: stopped; checkpoints may be retained or cleared, depending on the stop request;COMPLETED: a bounded input was exhausted;FAILED: the running job stopped unexpectedly.
The status response separates three facts:
| Field | Meaning |
|---|---|
state / observedState | Runtime state. Before the first observation, state is NEW and observedState is omitted. |
desiredState | The requested lifecycle intent, when available. |
displayState | The display phase, which can include DRAFT or STARTING. |
A saved draft can have displayState: DRAFT and hasArtifact: false. A known
pipeline requested to run can show STARTING before the first runtime
observation. Neither creates an observedAt timestamp. Once an observation
exists, observedAt records when it was captured; inspect its freshness
alongside logs and confirmed target progress.
When a job fails, the CLI status output includes failureCode and
failureMessage with the FAILED state. failureCode is the stable machine
key; failureMessage is the reader-facing explanation. Healthy states omit
these fields.
status --watch uses an authenticated WebSocket and emits runtime state
changes. For a known pipeline with no observation, it stays open without
inventing an initial state event. An unknown ID is refused. A failure frame
carries the same failure fields. A normal connection drop may be re-attached,
but a coded server refusal ends the watch and reports the code. Press
Ctrl+C to stop watching without stopping the pipeline.
Read the execution plan
When available, status includes a plan describing requested and effective
parallelism for each node, member counts, and batching. awaitingRebalance
lists cluster members that joined after the run was planned and have no part
of it until rebalance. Use the effective plan when checking execution; a
requested parallelism is a cluster-wide target, not a count per member. See
Pipeline reference.
Explain a lack of progress
In a connected session, run explain <pipeline-id>. The explanation uses the
same failure and freshness evidence as status. It can identify an old
observation or sustained lack of confirmed progress; NO_MATCH means no rule
matched, not that delivery is healthy.
A stale observation and a stalled pipeline are different conditions. The explanation considers an observation older than 30 seconds stale. Stall pressure requires at least 60 seconds without frontier movement; a brief pause alone is insufficient. Compare source activity, confirmed target positions, logs, and target records before restarting anything.
If no observation exists, the read returns monitor.no-observation. Missing
evidence must not become a healthy state in a dashboard.
Read metrics
metrics orders_to_operational_stateMetrics are an open map rather than a fixed schema. Depending on the active runtime path, the response can include numeric counters and a perTableOffset map of table names to opaque source positions.
For a pipeline that uses nest, the runtime reports one
nestDeadLettered.<namespace> entry for each namespace that could not place
changes into a document. The entry is absent when that namespace has no
discarded changes; the runtime does not emit one aggregate dead_lettered key.
Check the pipeline logs for the failure code and affected key. If you need a
pipeline-wide total, sum the namespace entries in your client.
An absent metric is unavailable, not zero. Do not build a strict parser that rejects new metric keys.
Unlike status, metrics, snapshot, and explanation reads require a runtime
observation. An applied pipeline without one returns monitor.no-observation.
A draft without a published artifact returns lifecycle.unknown-pipeline.
Output counters reflect target acknowledgements. Source-read, buffered, and
target-confirmed positions are different facts. The CLI renders serialized
positions as opaque fingerprints; these can identify a change but do not
reveal a binlog coordinate or LSN. A write-back summary also hides opaque
coordinates. Raw position JSON remains the format used for position edits.
See CLI position commands.
Read snapshot progress
snapshot orders_to_operational_stateSnapshot progress is per table. For chain-backed initial loads, confirmed
completion can survive a replacement run or member takeover. The current
run's snapshot.rows.read.<table> counter can therefore differ from the
persisted completion count. This retained completion does not apply to
snapshot_only runs.
A missing total must not be interpreted as 0% or 100%. Compare target counts
and representative keyed samples; an empty snapshot result alone does not
establish success or failure.
Read recent history
Choose a time range that contains your run. For example:
metrics orders_to_operational_state --from 2026-09-29T01:00:00Z --to 2026-09-29T02:00:00Z --resolution 5m --table ordersHistory reports target-confirmed output rates and lag for explicitly selected
tables. Lag is the age of the last target acknowledgement, not a count of
queued rows. Omitting --table omits table lag.
- Sampling defaults to once per 60 seconds; retention defaults to 15 days.
Operators can change
tapstate.metrics.history.sample-intervalandtapstate.metrics.history.retention. - Read the effective range and retention cutoff. Old samples may have expired.
- Keep resets and gaps visible. A missing rate or
NO_RETAINED_SAMPLESis not zero throughput. - Continue with
nextCursorwhile repeating the original query. Cursors expire after 10 minutes; restart the query if one expires. Results are eventually consistent, not a fixed audit snapshot.
See History parameters for limits,
resolutions, and error handling, or use
pipeline_metrics_history
from an AI agent.
Export metrics
Export is optional. Without an OTLP endpoint or Prometheus port, the server starts neither exporter. These settings do not disable built-in observations.
| Server property | Default | Use |
|---|---|---|
tapstate.metrics.export.otlp.endpoint | Unset | Collector URL; include /v1/metrics for HTTP/protobuf. |
tapstate.metrics.export.otlp.protocol | http-protobuf | Use http-protobuf or grpc. |
tapstate.metrics.export.otlp.interval | 60s | Push interval. |
tapstate.metrics.export.prometheus.port | Unset | Enable a separate scrape listener on this port. |
tapstate.metrics.export.prometheus.host | 127.0.0.1 | Interface for the scrape listener. |
Prometheus export has no built-in authentication and can expose pipeline, table, and namespace identifiers. If a scraper needs another bind address, restrict access to that network. It does not use the control API's bearer token.
Read and follow logs
logs orders_to_operational_state
logs orders_to_operational_state --follow
Logs are a bounded tail from the node serving the request. They are not a durable audit history or an aggregated multi-node log. An empty log result is valid when the pipeline has not logged on that node.
Connector log forwarding
Connector and PDK runtime logs are forwarded into the pipeline's log stream under the connector identifier (io.tapstate.connector.<connector-id>). Connector warnings and errors are preserved in the stream, while verbose debug chatter is filtered to protect the bounded tail. This enables operators to diagnose driver disconnects, authorization errors, retry loops, and schema anomalies directly via logs without host-level log access.
logs --follow opens an authenticated WebSocket and sends newly observed lines. Under a burst, a bounded tail can re-send a line when it re-tails after eviction; consumers should tolerate duplicates. A normal connection drop may be re-attached, but a server close carrying a coded refusal terminates the follow operation and reports the code instead of reconnecting indefinitely.
Build an evidence set
For a run review, capture:
- output from
tapstate versionand the pipeline revision; - final
status; - relevant metrics and per-table positions;
- the smallest useful log tail;
- source and target row counts;
- insert, update, and delete samples;
- timestamps and the expected result.
Remove secrets and customer data before sharing the evidence.